ty.

> ai / machine learning / robot learning / llms_

Thrushith Yelamanchili

AI and machine learning are what I care about most. Lately that means teaching a robot arm to pick things up from demos I recorded myself, then checking honestly whether the model got any better.

// 01

About

I build machine learning for robots. Models that watch a person do a task, then do it themselves.

I'm a Graduate Research Assistant at UMass Dartmouth working on robot learning. I record my own demos on a Hugging Face LeRobot SO-101 arm, fine-tune SmolVLA, a vision language action model with about 450M parameters, and test it against an ACT baseline. I built the rig too: two calibrated cameras on mounts I designed and 3D printed. My degree says data science, but AI and machine learning are the work I want to keep doing.

SO-101 pick and place, watched by two cameras. Roughly what my VLA policy does all day.

Robot learning

Imitation learning and vision-language-action models. SmolVLA vs ACT on a real SO-101 arm, trained on demos I collected myself.

Computer vision

Multi-camera perception for the robot, building footprint extraction from 1M+ geospatial records, and a GAN that colorizes photos.

Robust AI

Reproducing BadVLA backdoor attacks to see how robot policies break, and looking at failure modes instead of only success rates.

LLMs

Building with large language models, LangChain and retrieval-augmented generation.

96.98%
task success with my fine-tuned SmolVLA. The ACT baseline got 72.89%.
60%
faster processing after reworking feature extraction at Clove
118K
COCO images used to train my colorization GAN
// 02

Experience

  1. Dec 2025 → Aug 2026

    Graduate Research Assistant

    University of Massachusetts Dartmouth, robot learning

    • Fine-tuned and evaluated SmolVLA on teleoperation demos I collected on the SO-101, and benchmarked it against an ACT (Action Chunking Transformer) baseline on pick-and-place tasks.
    • Built the data collection pipeline for the LeRobot SO-101 6-DOF arm, recording demos across several manipulation tasks.
    • Set up and calibrated a synchronized dual-camera rig for multi-view observations, with 3D-printed mounts so the cameras land in the same spot every session.
    • Compared VLA and action chunking approaches on task success, generalization and failure modes.
    • Reproducing BadVLA backdoor attacks to study security holes in VLA-based manipulation policies.

    PyTorchLeRobotSmolVLAACTImitation Learning

  2. Dec 2023 → Mar 2024

    ML Engineer II, Machine Learning & GIS

    Clove Technologies, Visakhapatnam, India

    • Built a computer vision and deep learning pipeline that extracts building footprints from geospatial datasets with 1M+ spatial records.
    • Reworked the feature extraction step, which made processing 60% faster.
    • Wrote the preprocessing that turns raw geospatial data into ML-ready datasets, and tested how the pipeline held up as the data grew.

    Computer VisionDeep LearningPythonGIS

  3. Sep 2025 → Aug 2026

    Graduate Admissions Assistant

    University of Massachusetts Dartmouth

    • Built interactive Tableau and Excel dashboards to track admissions funnel metrics and spot enrollment trends across large institutional datasets.
    • Queried, maintained and validated applicant records in Slate CRM using SQL, and shaped the data into reports for stakeholders.
    • Put data validation, security, provenance and metadata practices in place to keep the data accurate and meet institutional compliance requirements.
    • Analyzed structured data with Python, SQL and Excel to give stakeholders insights they could act on.

    SQLPythonTableauSlate CRM

// 03

Selected projects

All repositories
P/01

Vision-Language-Action Policies for Robot Manipulation

I fine-tuned SmolVLA (about 450M parameters) on my own teleop dataset and put it up against an ACT baseline. Also in here: the vision processing for the two-camera setup and the scripts that make training and evaluation repeatable.
PyTorchLeRobotSmolVLAImitation Learning

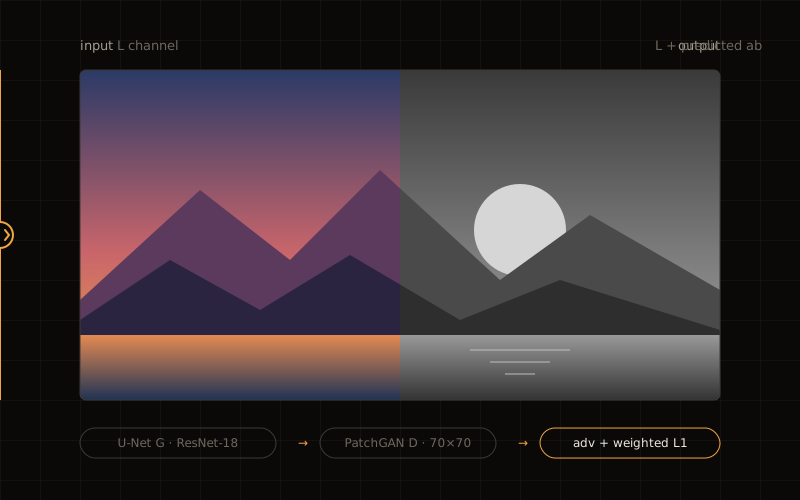
Illustration: a grayscale landscape being colorized by the GAN, with the generator, discriminator and loss pipeline below
P/02

Coloring Grayscale Photos with a GAN

A conditional GAN with a U-Net generator (ResNet-18 backbone) and a 70×70 PatchGAN discriminator, trained for 100 epochs on about 118K COCO images. It predicts color in CIE LAB space using adversarial plus weighted L1 loss. There's a React/Angular web demo so anyone can try it.

PyTorchGANsTransfer LearningReact

View source
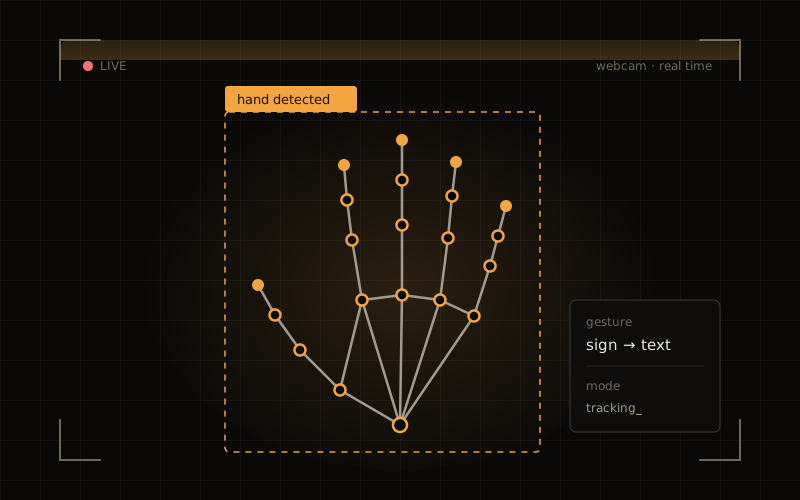
Illustration: a hand tracked by a webcam with its joints and a detection box highlighted
P/03

Real-time Hand Gesture Recognition

Reads sign language gestures live from a webcam. I built it to make it a bit easier for speech-impaired people to communicate.

Computer VisionOpenCVML

View source
// 04

Toolkit

> hover or tap a tool to see where I've used it_

Machine learning

LLMs

Evaluation

Core

Ship & store

// 05

Education

Degrees

  • M.S. Data Science University of Massachusetts Dartmouth
    GPA 3.94Aug 2026
  • B.Tech, AI & Data Science Vignan's Institute of Information Technology
    GPA 3.5May 2024

Certifications

  • Claude 101 Anthropic Academy
  • Docker & Kubernetes Udemy
// 06

Contact

Building robots, vision models, or something that has to ship? Let's talk.

thrushithy@gmail.com

message.sh